
Title: Reward Modelling: The Backbone of Safe and Alignable AI Systems
In modern AI systems—especially large language models—reward modelling is one of the most crucial components that ensures an AI behaves in ways that align with human values, goals, and expectations. But what exactly is reward modelling, and why does it matter?
What is Reward Modelling?
Reward modelling is a technique where AI systems are trained to understand what humans prefer or approve. Instead of relying only on raw data or programmed rules, the model learns from human feedback. This helps the AI choose the most helpful, safe, and context-appropriate response.
Why Do We Need Reward Modelling?
AI models generate many possible outputs. Not all of them are equally good for users. Reward modelling acts as a guide, ensuring that the model favors:
- Accurate information
- Safe, ethical behavior
- Helpful and relevant responses
- Compliance with user intent
This is key for building trustworthy AI systems that behave well even in complex situations.
How It Works (Simplified):
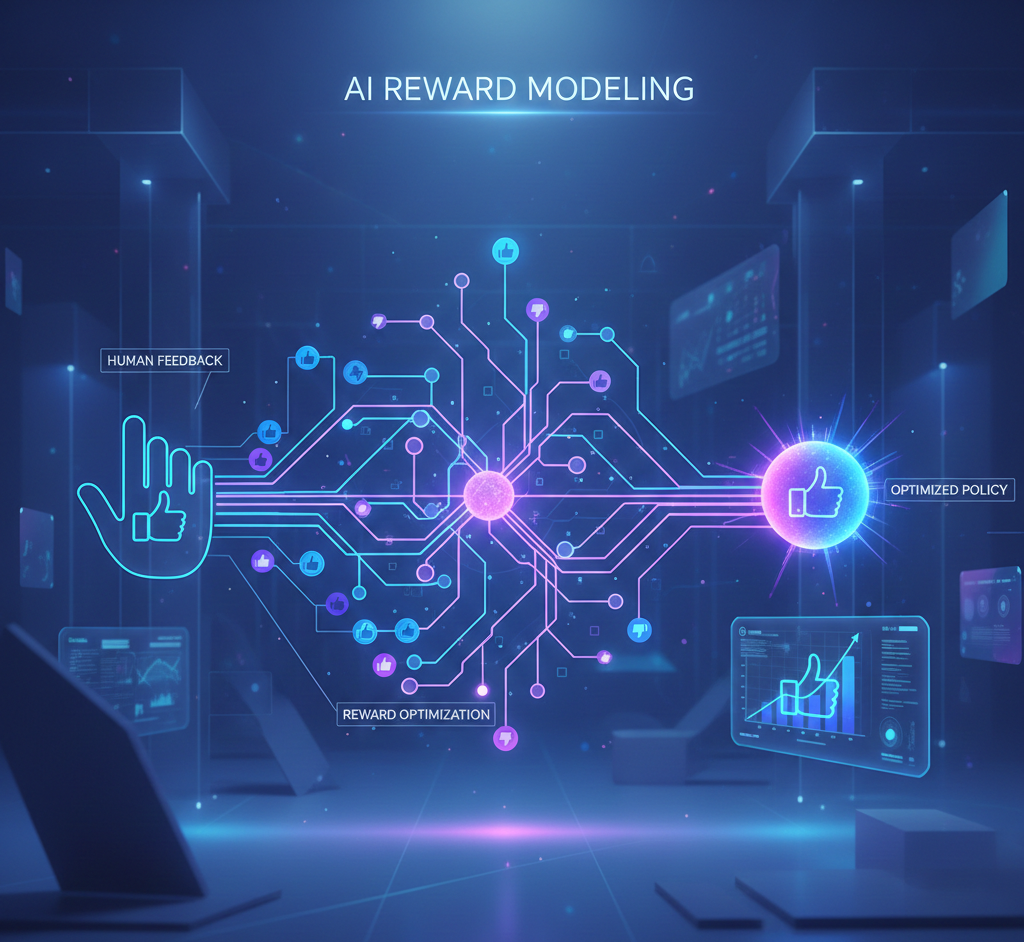
1. Human Feedback Collection:
Humans rate multiple outputs generated by the AI—for example, choosing which answer is better.
2. Reward Model Training:
A separate “reward model” learns patterns in these human preferences and predicts which outputs humans would prefer.
3. Reinforcement Learning with Human Feedback (RLHF):
The main AI model is trained using the reward model as a guide.
It receives:
- Positive reinforcement for preferred responses
- Negative signals for poor or unsafe responses
4. Continuous Improvement:
More human feedback → better reward model → better and safer AI behavior over time.
Where This Helps
- Safer conversational AI
- Content moderation
- Reducing hallucinations
- Ethical decision-making in autonomous systems
- Aligning AI with organizational policies
Reward modelling ensures that AI does not just generate output—but generates output that users want.